Tools come and go. Hadoop gave way to Spark, orchestrators multiplied, and every year brings a new “modern data stack.” Through all of it, SQL has stayed the one skill that nearly every data engineer uses daily. Whether you’re modeling a warehouse, debugging a broken pipeline, or tuning a query that takes forty minutes, your SQL fundamentals decide how fast and how safely you can move.
This guide covers the concepts that matter most in day-to-day data engineering, each with a diagram and a short example. The examples use standard SQL and adapt easily to Postgres, Snowflake, BigQuery, Redshift, or Spark SQL. Syntax differs slightly between engines, but the ideas travel.
Here is where SQL lives in a typical data platform. Almost every box below is built, tested, or debugged with SQL:

1. Joins and the Fan-Out Problem
Most people learn INNER, LEFT, RIGHT, and FULL OUTER joins early on. What separates experienced engineers is thinking about join cardinality: how many rows on one side match each row on the other.
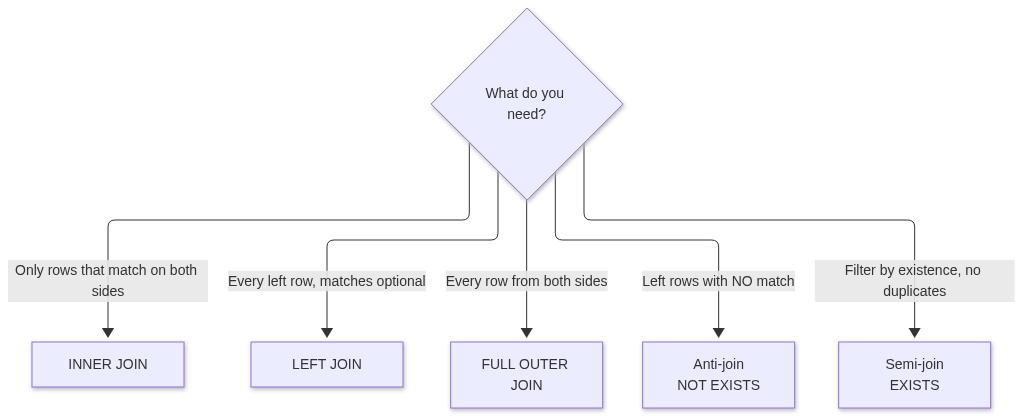
Start by choosing the join that matches the question you are asking:
The classic bug is the fan-out. Suppose you want revenue per customer:
-- Wrong: order_total is repeated once for every item in the order
SELECT o.customer_id, SUM(o.order_total) AS revenue
FROM orders o
JOIN order_items i ON i.order_id = o.order_id
GROUP BY o.customer_id;
An order with three items gets counted three times:

The fix is to aggregate at the right grain before joining, so the many-side is reduced to one row per order:
-- Right: collapse items to one row per order, then join
SELECT
  o.customer_id,
  SUM(o.order_total) AS revenue,
  SUM(i.item_count)  AS items_sold
FROM orders o
JOIN (
  SELECT order_id, COUNT(*) AS item_count
  FROM order_items
  GROUP BY order_id
) i ON i.order_id = o.order_id
GROUP BY o.customer_id;
And if you don’t need any item columns at all, skip the join entirely.
The two existence patterns look like this:
-- Anti-join: customers who have never ordered
SELECT c.customer_id
FROM customers c
WHERE NOT EXISTS (
  SELECT 1 FROM orders o WHERE o.customer_id = c.customer_id
);

-- Semi-join: customers with at least one order, with no duplicated rows
SELECT c.customer_id
FROM customers c
WHERE EXISTS (
  SELECT 1 FROM orders o WHERE o.customer_id = c.customer_id
);
A good habit: before trusting any join, check that the key you’re joining on is unique on the side you expect it to be.
2. Window Functions
Window functions compute values across a set of related rows without collapsing them the way GROUP BY does. They are arguably the single most valuable intermediate SQL skill for data engineers.
SELECT
  customer_id,
  order_date,
  amount,
  SUM(amount) OVER (
    PARTITION BY customer_id
    ORDER BY order_date
    ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW
  ) AS running_total,
  LAG(order_date) OVER (
    PARTITION BY customer_id ORDER BY order_date
  ) AS previous_order_date
FROM orders;
Every window function follows the same three-step mental model:
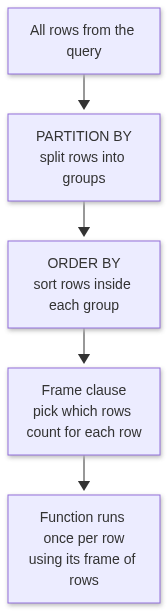
The functions you’ll reach for most often:
ROW_NUMBER, RANK, DENSE_RANK for ranking and picking the top N per group
LAG and LEAD for comparing a row to the one before or after it (churn, session gaps, period-over-period change)
SUM, AVG, COUNT with a frame for running totals and moving averages
FIRST_VALUE and LAST_VALUE for grabbing boundary values within a group
The three ranking functions differ only in how they treat ties. Given scores of 100, 90, 90, and 80:
| score | ROW_NUMBER | RANK | DENSE_RANK |
|---|---|---|---|
| 100 | 1 | 1 | 1 |
| 90 | 2 | 2 | 2 |
| 90 | 3 | 2 | 2 |
| 80 | 4 | 4 | 3 |
One gotcha: if you add ORDER BY to an aggregate window but omit the frame clause, most engines default to RANGE BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW. With RANGE, rows that tie on the sort column are treated as one peer group and get the same running total. For a true row-by-row running total, spell out ROWS BETWEEN, as the example above does.
3. Deduplication
Duplicates are a fact of life. Source systems retry, event streams deliver at-least-once, and backfills overlap. Sooner or later you will write a dedup query, and the standard pattern is ROW_NUMBER:
WITH ranked AS (
  SELECT
    *,
    ROW_NUMBER() OVER (
      PARTITION BY customer_id
      ORDER BY updated_at DESC
    ) AS rn
  FROM raw.customers
)
SELECT *
FROM ranked
WHERE rn = 1;

This keeps the latest record per customer. Snowflake, BigQuery, and Databricks offer a QUALIFY clause that lets you filter on the window function directly and skip the extra CTE:
SELECT *
FROM raw.customers
QUALIFY ROW_NUMBER() OVER (
  PARTITION BY customer_id
  ORDER BY updated_at DESC, ingested_at DESC  -- ingested_at breaks ties
) = 1;
The important design decision is the tiebreaker. If two rows share the same updated_at, the result is nondeterministic unless you add a secondary sort column. Non-deterministic dedup is a frequent cause of “the numbers changed between runs” bugs.
4. CTEs and Query Structure
Common Table Expressions (CTEs) let you break a complex query into named, readable steps:
WITH daily_orders AS (
  SELECT customer_id, CAST(created_at AS DATE) AS order_date, SUM(amount) AS daily_total
  FROM orders
  GROUP BY 1, 2
),
active_customers AS (
  SELECT customer_id
  FROM daily_orders
  GROUP BY customer_id
  HAVING COUNT(*) >= 3
)
SELECT d.*
FROM daily_orders d
JOIN active_customers a USING (customer_id);
Think of a chain of CTEs as a small pipeline inside a single query:

CTEs are mostly about readability and maintainability, which matter a great deal when someone else (or future you) has to debug the query at 2 a.m. Two things to keep in mind:
Depending on the engine, a CTE may be inlined or materialized. In some databases, referencing the same CTE twice recomputes it; in others it’s computed once. Check your engine’s behavior when performance matters.
Recursive CTEs handle hierarchical data such as org charts, category trees, and bill-of-materials structures, which are common in warehouses.
5. Aggregation, GROUP BY, and Conditional Aggregation
Beyond COUNT and SUM, strong SQL means knowing how to compute several metrics in a single pass using conditional aggregation:
SELECT
  order_date,
  COUNT(*) AS total_orders,
  SUM(CASE WHEN status = 'refunded' THEN 1 ELSE 0 END) AS refunded_orders,
  SUM(CASE WHEN status = 'completed' THEN amount ELSE 0 END) AS completed_revenue
FROM orders
GROUP BY order_date;
The difference between WHERE and HAVING comes down to the logical order of execution, which is different from the order you write the clauses in:

Because WHERE runs before grouping, it can’t see aggregates, so a condition like COUNT(*) >= 3 belongs in HAVING. Going the other way, filtering raw rows in WHERE is cheaper than doing it in HAVING, because it shrinks the data before aggregation. The same order explains why you can’t reference a window function in WHERE: it hasn’t been computed yet.
Also know when to reach for GROUPING SETS, ROLLUP, and CUBE to produce subtotals and multiple aggregation levels in one query, and COUNT(DISTINCT ...) versus approximate alternatives (such as HyperLogLog-based functions) when you’re counting at massive scale.
6. NULL Handling
NULL means “unknown,” not “zero” or “empty,” and it behaves in ways that surprise people:
NULL = NULLis not true. UseIS NULLandIS NOT NULL.NOT INreturns no rows if the subquery contains even one NULL. PreferNOT EXISTS.Aggregates like
SUMandAVGignore NULLs, butCOUNT(*)counts every row whileCOUNT(column)skips NULLs.Joins never match on NULL keys, so rows with NULL join keys silently disappear from inner joins.
Here is why the NOT IN trap bites, step by step:

Use COALESCE to supply defaults and NULLIF to avoid divide-by-zero errors:
SELECT revenue / NULLIF(orders, 0) AS avg_order_value
FROM daily_metrics;
Many subtle data quality bugs trace back to NULL semantics, so it pays to be deliberate.
7. Indexes and Execution Plans
Writing correct SQL is step one. Writing SQL that runs efficiently is what makes you valuable at scale. Learn to read an execution plan with EXPLAIN (or EXPLAIN ANALYZE). A plan is a tree, and you read it from the leaves upward:

When reading a plan, look for:
Full table scans where an index or partition filter should apply
Join strategy: nested loop, hash join, or merge join, and whether the planner chose well
Row estimate mismatches, where the optimizer expected 100 rows and got 10 million, which usually signals stale statistics
Expensive sorts and shuffles, especially in distributed engines
In row-oriented databases, indexes (B-tree, composite, covering) are the main speed tool. Note that an index on (customer_id, order_date) helps queries filtering on customer_id, or on both columns, but usually can’t help a query that filters on order_date alone (some newer engines add skip-scan optimizations, so always confirm with EXPLAIN). Also avoid wrapping indexed columns in functions inside WHERE clauses, because WHERE DATE(created_at) = '2026-01-01' often prevents the index from being used. A range filter such as created_at >= '2026-01-01' AND created_at < '2026-01-02' is usually index-friendly.
Columnar warehouses like Snowflake, BigQuery, and Redshift work differently. They rely less on traditional indexes and more on the next concept.
8. Partitioning, Clustering, and Pruning
In large-scale analytical systems, the fastest data to process is the data you never read. Partitioning splits a table into segments (usually by date), and clustering or sort keys organize data within those segments so the engine can skip irrelevant blocks.
-- BigQuery syntax
CREATE TABLE events (
  event_id BIGINT,
  user_id BIGINT,
  event_type STRING,
  event_date DATE
)
PARTITION BY event_date
CLUSTER BY user_id;
Here is pruning in action for a query that asks about a single day:
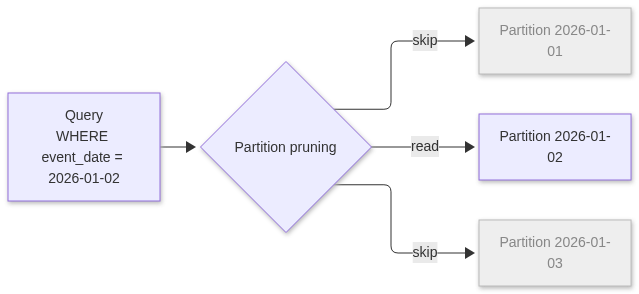
The payoff only arrives if your queries filter on the partition column, so always include a date filter on big fact tables. Avoid partitioning on columns with extremely high cardinality, which creates thousands of tiny partitions and hurts more than it helps. Every platform spells this differently (Snowflake manages micro-partitions automatically and lets you define a clustering key, Redshift uses distribution and sort keys, and PostgreSQL uses declarative PARTITION BY RANGE), but the idea is the same everywhere.
9. Incremental Loads, MERGE, and Idempotency
Reprocessing an entire table every night works until the table gets big. Production pipelines load data incrementally, and that introduces a critical requirement: idempotency. Running the same job twice must produce the same result as running it once, because retries and reruns are inevitable.
The workhorse for this is MERGE (also called upsert):
MERGE INTO dim_customer AS target
USING staging_customer AS source
  ON target.customer_id = source.customer_id
WHEN MATCHED AND source.updated_at > target.updated_at THEN
  UPDATE SET
    name = source.name,
    email = source.email,
    updated_at = source.updated_at
WHEN NOT MATCHED THEN
  INSERT (customer_id, name, email, updated_at)
  VALUES (source.customer_id, source.name, source.email, source.updated_at);
Here is the decision logic MERGE applies to every incoming row:

Re-running the same batch is harmless: the second pass finds nothing newer to apply.
Two practical notes. MERGE is available in Snowflake, BigQuery, Databricks, SQL Server, Oracle, and PostgreSQL 15 and later; older PostgreSQL versions use INSERT ... ON CONFLICT DO UPDATE for the same purpose. And a basic MERGE never notices rows that disappear from the source, so decide up front how deletes are handled: a soft-delete flag in the source, or a WHEN NOT MATCHED BY SOURCE clause where your engine supports it.
Other idempotent patterns include delete-then-insert for a given partition and overwriting a single partition atomically. Whichever you choose, deduplicate staging first (see section 3), because a MERGE with duplicate source keys can fail or produce unpredictable results.
10. Slowly Changing Dimensions (SCD Type 2)
Business attributes change: a customer moves, an account upgrades its plan, a product changes category. If you overwrite the old value, you lose history, and reports run against past periods will change retroactively. SCD Type 2 solves this by keeping every version of a record with validity dates:
| customer_id | plan | valid_from | valid_to | is_current |
|---|---|---|---|---|
| 101 | Free | 2025-01-01 | 2025-08-15 | false |
| 101 | Pro | 2025-08-15 | 9999-12-31 | true |
Notice that the old row’s valid_to equals the new row’s valid_from. Treat valid_to as exclusive, a half-open interval, so the versions tile the timeline with no gaps and no overlaps. Mixing inclusive and exclusive end dates is a well-known SCD2 bug, and it silently drops or double-counts rows on boundary days.
When a change arrives, two things happen together:

To analyze data as of a point in time, join the fact table to the dimension on the key and a date range:
SELECT f.order_id, d.plan
FROM fact_orders f
JOIN dim_customer_scd2 d
  ON d.customer_id = f.customer_id
 AND f.order_date >= d.valid_from
 AND f.order_date < d.valid_to;
In practice, run both steps in a single transaction (see section 12), so a failure between them can never leave a customer with no current row or two current rows.
11. Data Modeling: Normalization, Star Schemas, and Grain
SQL skill isn’t only about queries; it’s also about the shape of the tables you query.
Normalization (3NF) reduces redundancy and protects integrity. It’s the standard for transactional systems.
Dimensional modeling (star and snowflake schemas) organizes analytical data into fact tables (events and measurements) surrounded by dimension tables (descriptive context). It trades some redundancy for simpler, faster analytics.
A star schema looks like this, with one central fact table and dimensions radiating out:
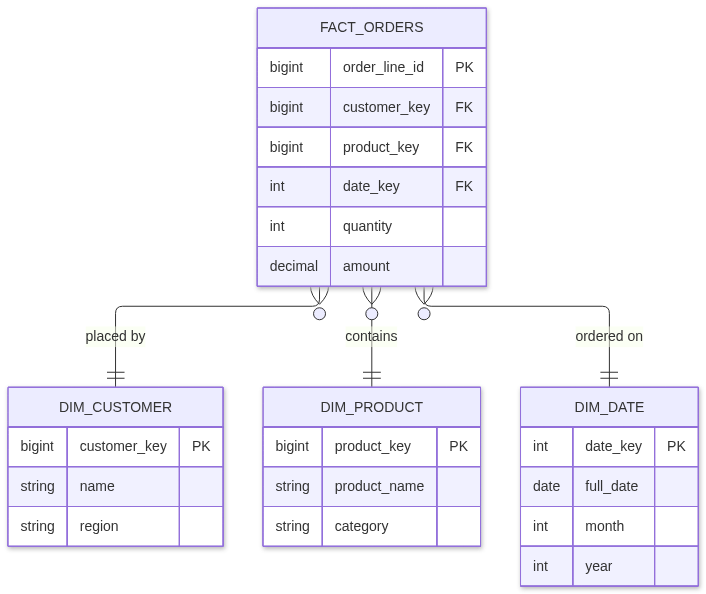
The most important modeling concept is grain: a precise statement of what one row in a table represents. “One row per order line item” is a grain. Decide it first, write it down, and make sure every column respects it. Most fan-out bugs and double-counting errors are really grain errors in disguise.
12. Transactions, ACID, and Isolation Levels
A transaction groups statements so they succeed or fail together. The ACID properties (Atomicity, Consistency, Isolation, Durability) are what make relational databases trustworthy.

For data engineers, the practical takeaways are:
Wrap multi-step loads in a transaction where your platform supports it, so a half-finished load never becomes visible to downstream consumers.
Understand isolation levels (read committed, repeatable read, serializable) and the anomalies they prevent, such as dirty reads and phantom reads, especially when pipelines read from live operational databases.
Know that many cloud warehouses and lakehouse table formats (Delta Lake, Iceberg, Hudi) provide transactional guarantees on top of object storage, which is what makes safe concurrent writes and reliable MERGE operations possible.
13. Dates, Time Zones, and Semi-Structured Data
Two things cause a disproportionate share of pipeline bugs: time and nested data.
Time zones. A “day” depends on whose clock you use. An order placed at 11:30 p.m. in New York on January 1 is already January 2 in UTC, so a daily revenue report can move orders between days depending on the zone. The safe convention is to store timestamps in UTC and convert to the business time zone only at the reporting edge:
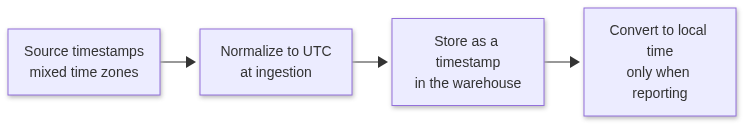
-- PostgreSQL: created_at is a timestamptz stored in UTC
SELECT
  DATE_TRUNC('day', created_at AT TIME ZONE 'Asia/Kolkata') AS order_day_ist,
  COUNT(*) AS orders
FROM orders
GROUP BY 1;
Also distinguish event time (when something happened) from load time (when it reached your warehouse). An incremental job that filters only on load time can mislabel late-arriving records, and one that filters only on event time can miss them entirely, so many teams reprocess a small trailing window on every run.
Semi-structured data. Modern sources deliver JSON constantly, and warehouses have native types for it (JSONB in PostgreSQL, VARIANT in Snowflake, JSON, STRUCT, and ARRAY in BigQuery). Extract the fields you need into typed columns in your staging layer so downstream models don’t repeat the parsing:
-- PostgreSQL JSONB: pull fields out and flatten an array
SELECT
  e.event_id,
  e.payload ->> 'user_id' AS user_id,
  item ->> 'sku'          AS sku
FROM raw.events e,
     jsonb_array_elements(e.payload -> 'items') AS item;
Flattening an array produces one row per element, which is another route to the fan-out problem from section 1. Re-check your grain every time you unnest.
14. Data Quality Checks in SQL
A pipeline that runs successfully but produces wrong data is worse than one that fails loudly. Get comfortable writing validation queries and wiring them into your workflow, whether through dbt tests, Great Expectations, or plain SQL assertions:
-- Duplicate primary keys
SELECT order_id, COUNT(*)
FROM fact_orders
GROUP BY order_id
HAVING COUNT(*) > 1;

-- Orphaned foreign keys
SELECT f.order_id
FROM fact_orders f
LEFT JOIN dim_customer c ON c.customer_id = f.customer_id
WHERE c.customer_id IS NULL;

-- Freshness
SELECT MAX(loaded_at) AS last_load FROM fact_orders;
Treat checks as a gate between your transformations and your consumers:

Check uniqueness, nullability, referential integrity, accepted values, row-count reconciliation against the source, and freshness. These checks are cheap to write and save hours of debugging.
Putting It All Together
If you’re looking for a learning path, here’s a sensible order:
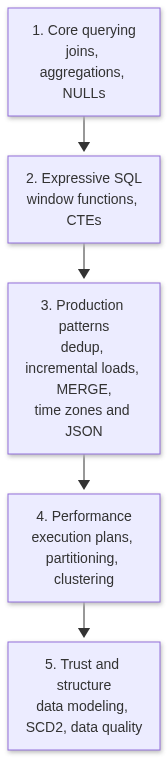
Each stage builds on the last: window functions are easier once joins feel natural, and incremental loading only makes sense once you can deduplicate.
Quick Reference
| Concept | Remember this | Classic pitfall |
|---|---|---|
| Joins | Know the grain on both sides | Fan-out inflates sums |
| Window functions | Partition, order, then frame | Default RANGE frame with tied values |
| Deduplication | ROW_NUMBER with a tiebreaker | Non-deterministic results between runs |
| CTEs | Name each step of the pipeline | Recomputation in some engines |
| Aggregation | WHERE filters rows, HAVING filters groups | Filtering in the wrong clause |
| NULLs | NULL means unknown | NOT IN with a NULL in the list |
| Execution plans | Read from the leaves upward | Stale statistics, unexpected full scans |
| Partitioning | Filter on the partition column | Too many tiny partitions |
| MERGE | Deduplicate the source first | Duplicate source keys, unhandled deletes |
| SCD2 | Use half-open date ranges | Gaps or overlaps in history |
| Data modeling | Declare the grain up front | Mixed grains in one table |
| Transactions | All or nothing | Half-loaded tables visible downstream |
| Dates and JSON | Store UTC, flatten deliberately | Shifting day boundaries, unnest multiplying rows |
| Data quality | Gate before publishing | A green pipeline with wrong data |
The best way to internalize all of this is to build something real: pull a public dataset into a warehouse, model it into a star schema, load it incrementally, and add tests. Every concept above will come up, and each one will stick far better than it would from reading alone.
SQL may be decades old, but depth in SQL is still one of the clearest signals of a strong data engineer. Invest in the fundamentals, and every new tool you pick up will make more sense.
Published via ZyVOP — Write once in Markdown, auto-backup to GitHub, and syndicate to Dev.to, Medium & Hashnode in 1 click.
About the author
- One platform to write, cross-post to Dev.to, Medium, WordPress, Hashnode, and Bluesky, and protect your SEO with canonical links. Zero paywalls and full content ownership.
Comments
Join the discussionNo comments yet. Be the first to comment.