Gemini 4 Argon: Google's new flagship is here, and almost nobody can use it yet
It leads on knowledge work, trails on a few coding tests, and is limited to cyber defenders for now. Here's what Google actually shipped.
Gemini 4 Argon is the model Google has been promising since May. It's out, sort of.
Google announced it on Wednesday, September 30. Right now, the only people who can use it are trusted cyber defenders in Google's Fairwind Program. Everyone else is waiting.
The wait may be worth it. On Google's own charts, Argon beats OpenAI's GPT-6 Astra, Anthropic's Claude Fable 5.1 and Claude Opus 5.5 on 13 of 18 benchmarks. But the five it loses are mostly coding and science tests, and that matters if you build software for a living.
The short version
Best at knowledge work. It leads on finance, legal, business automation and long-context tests.
Mixed on coding. It sets a new high on DeepSWE v1.1 but finishes last on two other coding benchmarks.
Up to 1 million output tokens in one response, up from 64K on earlier Gemini models.
Introductory pricing: $2 per million input tokens and $10 per million output tokens.
Access is limited. Google says "rolling out soon" and hasn't given dates.
Why it took so long
Google said at its I/O conference in May that a new Pro-tier model, Gemini 3.5 Pro, was on the way. That model never shipped. Google put out a series of Flash models instead, including Gemini 3.8 Flash.
Meanwhile OpenAI and Anthropic kept moving at the top end. Axios described Argon as a long-awaited answer to both.
Before launch, Bloomberg reported that some people inside Google worried Argon wouldn't match its rivals. The published numbers are better than that worry suggests, at least where Google chose to compete.
Who gets it, and when
Google is releasing Argon in stages. It is also taking part in the US government's voluntary process that gives officials access to frontier models before release.
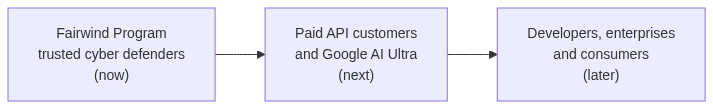
Google says it wants feedback from early testers so it can tighten the guardrails before opening the doors wider. There are no dates yet, so check Google's announcement for updates.
What it costs
Introductory pricing is $2 per million input tokens and $10 per million output tokens. Cached input tokens get a 95% discount off the input price.
The introductory period will end. After that, the price goes to $4 per million input tokens and $20 per million output tokens.
Output pricing deserves attention because of the new 1M-token output limit. One response that uses all of it would cost about $10 at the introductory rate and $20 at the standard rate. Most responses will be far shorter, but long agent runs can add up quickly.
The benchmarks
These scores come from Google's launch charts, as compiled by The New Stack. Best score in each row is in bold.
| Benchmark | Gemini 4 Argon | GPT-6 Astra | Claude Fable 5.1 | Claude Opus 5.5 |
|---|---|---|---|---|
| Vals Index | 68.9% | 63.1% | 65.8% | 67.0% |
| AutomationBench | 51.3% | 41.4% | 31.4% | 42.5% |
| Vals Finance Agent v2 | 65.4% | 53.5% | 58.9% | 58.6% |
| Harvey Legal Agent Benchmark | 19.6% | 5.4% | 6.7% | 3.8% |
| DeepSWE v1.1 | 77.9% | 74.1% | 67.4% | 74.2% |
| FrontierSWE v2 | 55.0% | 65.5% | 56.3% | 62.3% |
| Vibe Code Bench | 91.9% | 89.6% | 90.3% | 90.3% |
| Terminal-Bench 4.0 | 57.4% | 58.2% | 57.9% | 66.4% |
| PostTrainBench | 45.3% | 44.3% | 40.2% | 49.3% |
| Terminal-Bench Science 0.1 | 57.6% | 68.1% | 52.6% | 63.3% |
| RiemannBench | 76.0% | 72.0% | 65.6% | 69.6% |
| GraphWalks (up to 128K) | 99.7% | 98.7% | 91.4% | 90.6% |
| GraphWalks (256K to 1M) | 84.2% | 71.8% | 65.0% | 66.8% |
| Agent's Last Exam | 39.5% | 34.2% | n/a | 38.2% |
| OSWorld-2.0 (offline subset) | 69.2% | 72.6% | n/a | n/a |
| Chartography | 71.6% | 71.0% | 46.2% | 66.3% |
| LVBench | 91.7% | 87.5% | 79.7% | 83.7% |
| CWE-bench v1 | 68.0% | 68.0% | 58.0% | 67.0% |
Two things to keep in mind. Almost every number here comes from Google, and the model isn't broadly available to test. The exception is the Vals Index, where Vals AI confirmed on launch day that Gemini is on top for the first time.
Also, CWE-bench v1 is a tie with GPT-6 Astra (and xAI's Grok 4.7). The major labs ran their models in their own agent tools, so that result measures the model and its harness together.
Knowledge work is the real story
Argon's biggest leads are on the kind of work that fills a business day.
On Zapier's AutomationBench, it scores 51.3%, almost nine points ahead of Opus 5.5. On GraphWalks with inputs between 256K and 1M tokens, it beats GPT-6 Astra by more than 12 points. On Vals Finance Agent v2, which tests multi-step financial research, it leads by about six points.
Harvey's legal benchmark has the widest gap. Argon's 19.6% is nearly triple Fable 5.1's score. It also means Argon completes only about one task in five, so the whole field has a long way to go.
Google also claims an edge when the work involves visuals. Argon leads on LVBench, which tests long-video understanding, with 91.7%. It also leads on Chartography.
On several of these tests, the margin is under two points: Vals Index, Vibe Code Bench, Agent's Last Exam, Chartography and the shorter GraphWalks test. Those are leads, but not blowouts.
Coding: strong, not dominant
Google calls out coding as a strength, and the headline number backs it up. Argon scores 77.9% on DeepSWE v1.1, a benchmark built around long, real-world software engineering tasks.
The rest of the picture is less clean. Argon comes last on FrontierSWE v2, where GPT-6 Astra leads by 10.5 points. It also comes last on Terminal-Bench 4.0, where Opus 5.5 leads by 9 points.
Its other coding win is Vibe Code Bench, but all four models score above 89% there.
If your daily work is terminal-heavy agent coding, treat the launch charts as a reason to test, not a reason to switch.
One million output tokens
One million input tokens is standard at the frontier now. Output limits haven't kept up. Earlier Gemini models topped out at 64K.
Google says that extra room lets the model think for hundreds of thousands of tokens in a single run and work through hard problems in one pass. That's most useful for large rewrites, long analyses and agent runs that would otherwise be chopped into pieces.
Most tasks won't need anywhere near that much. And as the pricing section shows, you pay for every token.
What Google did with it first
Google shared a few internal examples. They're Google's own claims, but they're specific.
Memory in data centers. A team of Argon agents analyzed fleet-wide profiling data and applied memory optimizations on its own. Google says this frees over 300 TiB once rolled out, with total savings estimated at 500 TiB to 1 PiB.
Quantum research. Argon helped optimize the resources (qubits times gates) needed by subroutines that bottleneck important applications. In one case it beat the published baseline by 40% in minutes.
Rewriting C and C++ in Rust. Argon agents are working on projects that range from tens of thousands of lines in libraries like re2 and libgav1 up to more than 800,000 lines for the Fuchsia Zircon kernel.
The Rust work comes with a caveat that Google states itself. Given how critical many of these systems are, the rewrites are going through automated and manual audits, emulation testing and review before they reach production.
The libgav1 result is the one to remember. Starting from an existing Rust port of Google's open source video decoder, the agents replaced 32,000 lines of SIMD code with safe Rust the compiler can vectorize on its own. Google says the result runs 2.7 times faster than the Rust port, with identical video output.
The cybersecurity angle
Cyber is why access is so tight. Google trained Argon to find, validate and patch serious software vulnerabilities without a human steering each step.
For Fairwind members and its own internal teams, Google is releasing Argon without cyber guardrails. Defenders get the full capability. Everyone else will get a version with safeguards when it opens up.
Wiz is already using it through its Scan for Good program, which looks for exposures in critical public infrastructure at no cost. Google says Argon found a critical flaw in healthcare software used by hospitals worldwide, one that earlier frontier models had missed.
On the numbers, Argon scores 85.8% on Google's internal vulnerability discovery benchmark and 70.9% on Wiz's penetration testing benchmark. Google only compares those with its own Gemini 3.8 Flash Cyber, which scored 71.0% and 58.2%. That shows progress over Google's previous model. It says nothing about how Argon stacks up against rivals on those tests.
Safety work before wide release
Google lists four areas it is still strengthening before a broad release.
Misuse. The model is built to refuse cyber and chemical, biological, radiological and nuclear attacks while still helping with legitimate research. Google is also monitoring the model's internal activations to catch misuse.
Prompt injection. Google calls Argon its most resilient model yet and says it leads Gray Swan's indirect prompt injection benchmark.
Misalignment. Monitors watch Argon's reasoning and actions and stop execution when needed. Google says it kept findings from its own training-run monitoring out of training, so the model isn't taught to hide its reasoning.
Hardening systems. Sandboxed test environments are isolated and sealed before high-risk training or evaluations begin.
Google also urged the rest of the industry to keep model reasoning transparent while capabilities rise.
What to do now
If you work in security, look at the Fairwind Program. That's the only way in today.
If you build tools for finance, legal or business automation, Argon is the model to test first once it opens up.
If you're a developer, don't plan around it yet. Run it on your own tasks when you get access, especially long agent workflows where Terminal-Bench and FrontierSWE results suggest it may fall short.
If you're budgeting, model the standard price of $4 and $20, not the introductory one.
Bottom line
Gemini 4 Argon puts Google back in the frontier conversation. It looks strongest where companies spend money: research, documents, spreadsheets, workflows and long context. Coding is competitive but not a clear win.
The caveat is the launch itself. Most of the evidence is Google's, and almost no one outside Fairwind can test it. The real verdict will come when it reaches the API.
Sources
Google: Gemini 4 Argon, our next era of frontier intelligence
The New Stack: Gemini 4 Argon is here. It's great, and you can't have it yet
Published via ZyVOP — Write once in Markdown, auto-backup to GitHub, and syndicate to Dev.to, Medium & Hashnode in 1 click.